About the Free-OCR.net OCR service and editorial standards
Free-OCR.net turns images and scanned documents into reviewable text, then explains the choices, limits, and file handling behind the result.
- Purpose
- Reviewable OCR
- Product
- Tools and practical guides
- Standard
- No invented accuracy claims
Why Free-OCR.net exists
OCR is useful only when the result is easy to inspect, correct, and move into the next task.
Many OCR pages reduce the job to an upload button and an unexplained accuracy promise. That conceals the choices that change the result: capture quality, rotation, language, page segmentation, layout, export type, and the cost of a wrong character. Free-OCR.net places those choices beside the tool instead of hiding them.
The site combines working OCR routes with a focused OCR learning library. The tool produces a draft; the guides help a user decide whether that draft is ready to copy, needs page-level review, or should be transcribed another way.
Product principles
Four rules shape the interface, exports, and guidance.
Match the route to the source
A screenshot, camera photo, scanned PDF, table, formula, and handwritten note create different review problems. Each route starts with defaults and instructions suited to that source.
Keep uncertainty visible
Confidence, page results, structured diagnostics, and editable output help users find weak areas. A confidence score is a triage signal, not proof.
Preserve useful structure
Markdown, Word, JSON, CSV, searchable PDF, and task-specific exports serve different downstream jobs. No single format is described as universally best.
Explain the data path
The security page separates local retention from remote processing so a short-lived result link is never presented as deletion everywhere.
How the service works
The recognition result and the review diagnostics can come from separate passes.
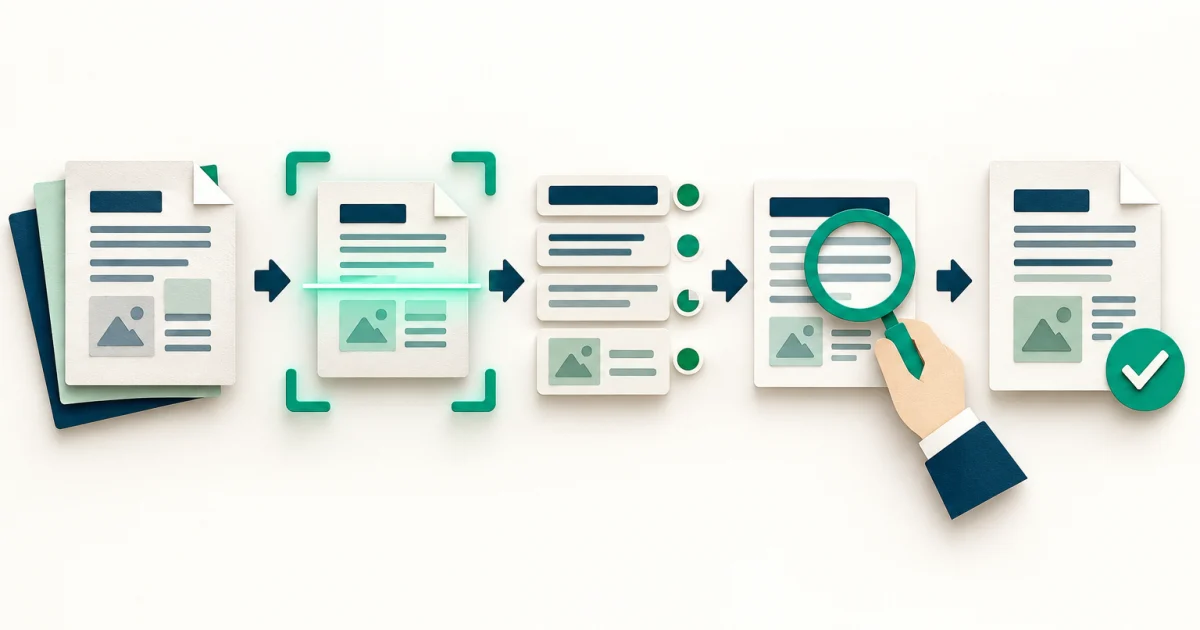
- Validate the source.The server checks the filename, file type, size, image dimensions, and requested PDF range before recognition.
- Prepare a bounded working copy.Orientation, scaling, and an optional cleanup preset are applied in a request-specific workspace.
- Recognize and diagnose.Structured document OCR supplies primary text when available; a local Tesseract pass supplies word boxes and confidence diagnostics.
- Build reviewable exports.The result page exposes readable text, editable formats, structured data, and original-layout options where the route supports them.
- Expire local results.Guest and account copies follow the retention windows stated in the product and policies.
The exact engine behavior, long-PDF batching, preprocessing, and confidence formula are documented in the OCR methodology.
Who publishes and reviews the guides
The byline names an accountable publishing function, not an invented expert persona.
The Free-OCR.net editorial desk is an organizational byline for the people maintaining this service and its documentation. It does not imply a professional licence, academic appointment, or independent laboratory.
Technical pages should identify the method behind a claim, link to relevant primary sources, distinguish observation from recommendation, and name important limitations. Drafting and quality checks may be automated, but publication responsibility remains with the operator of the editorial queue under the full editorial quality standard.
Claims we make carefully
Useful restraint is more credible than a universal accuracy number.
What we can document
- Which engine path completed a result
- Which preparation and page settings were requested
- Which exports were generated
- How the local confidence diagnostic is calculated
- When local guest and account copies expire
What we do not claim
- Perfect OCR accuracy
- Human review of every upload
- A benchmark that was not actually run
- Professional accreditation or legal compliance certification
- Suitability for consequential use without verification
Choose where to start
Begin with the source you have or the decision you need to make.
Page reviewed 25 October 2026