OCR methodology and confidence reporting
A reproducible description of the live recognition path, preparation choices, long-PDF handling, diagnostics, exports, and known limits.
- Primary path
- Structured document OCR
- Diagnostics
- Local Tesseract pass
- Long PDF batches
- Up to 8 pages per remote request
The recognition pipeline
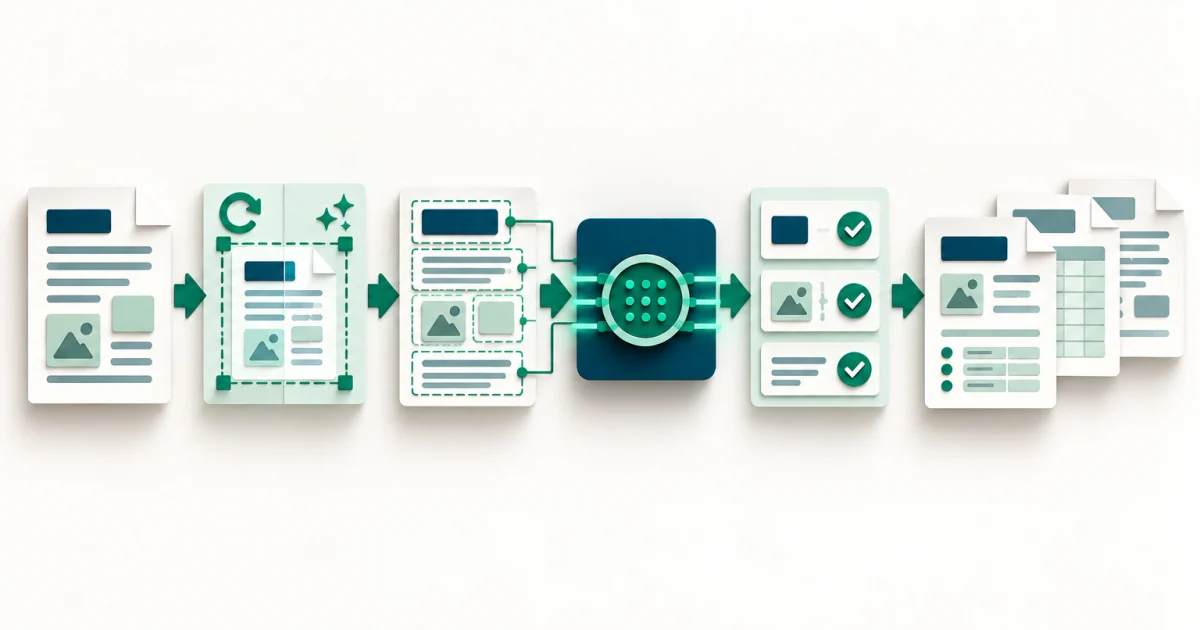
Free-OCR.net separates primary text generation from local review diagnostics.
- 1
Validate
Confirm format, size, pixels, PDF signature, and page range.
- 2
Normalize
Correct EXIF orientation and bound oversized images.
- 3
Prepare
Apply the selected cleanup and page-layout assumption.
- 4
Recognize
Run structured document OCR and a local diagnostic pass.
- 5
Structure
Normalize readable text, Markdown, tables, fields, or formulas.
- 6
Export
Create review and download formats, then remove working files.
When configured, Wallpapers.com Document OCR supplies the primary structured result using Baidu Unlimited-OCR. Tesseract runs separately on the application host to supply local word boxes and confidence diagnostics. Every completed result identifies the engine path that supplied its text.
English and Chinese language handling
Automatic mode recognizes the visible language without translating it.
With structured OCR available, Automatic is used for English, Chinese, or a document containing both. The recognition prompt asks for transcription in reading order while preserving the source language, punctuation, and simplified or traditional character forms.
The local Tesseract diagnostic uses an installed language model and may cover fewer languages than the primary structured result. For an automatic or bilingual job, Free-OCR.net does not quietly return a weak English-only local fallback when Chinese may be present. It stops with a retry message unless the local result is a substantial high-confidence English result and the route permits that fallback.
Image preparation and layout modes
The presets change the local diagnostic image, not the meaning of the source.
| Control | What it does | When it helps |
|---|---|---|
| Original image | Corrects orientation, converts to a bounded RGB PNG, and skips grayscale cleanup filters | Color documents, screenshots, diagrams, and already-clean scans |
| Clean document | Grayscale, conservative autocontrast, median noise reduction, and restrained sharpening | Ordinary printed pages with mild noise or uneven contrast |
| Faint print | Applies the clean-document sequence with stronger contrast | Light copies where characters need separation from the background |
| Automatic layout | Uses Tesseract page segmentation mode 3 | Mixed pages where layout should be detected |
| Single text block | Uses Tesseract page segmentation mode 6 | One regular body of text |
| Sparse labels | Uses Tesseract page segmentation mode 11 | Interface labels, forms, signs, or separated text regions |
These modes are page-organization assumptions, not quality grades. A stronger filter can erase punctuation or thin strokes, so the source preview remains important.
PDF rendering, chunking, and retries
Long PDFs are divided so one provider timeout does not discard the complete job.
- Selected pages are rendered locally to PNG at 300 dpi for the diagnostic pass.
- Standard PDF routes accept a selected range of up to 25 pages; Long PDF OCR accepts up to 100.
- Remote recognition receives PDF batches of up to 8 pages.
- A batch exceeding the remote file limit is split before submission.
- A timed-out or retryable batch is retried with bounded backoff and can be divided into smaller page ranges.
- The processing page reports the active source-page range so a long job does not appear frozen at one percentage.
Single images first try the provider's detailed gundam mode, then the base mode when needed. Multi-page PDF recognition uses the base path. This matches the current Unlimited-OCR distinction between single-image and multi-page inference modes.
How confidence is calculated
The displayed value is a local diagnostic average, not verified accuracy.
The application includes non-empty Tesseract tokens with a non-negative confidence value and reports their arithmetic mean. Page confidence values are averaged for the overall local diagnostic.
When structured remote OCR supplies the primary text, the local score may not map word-for-word to that result. Use it to prioritize comparison with the source, not to certify a page or field. The confidence-score guide gives a practical review workflow.
Exports, task modes, and limits
Each output preserves a different kind of information.
| Output | Designed to preserve | Important limitation |
|---|---|---|
| TXT | Readable primary text | Does not preserve page design |
| Markdown | Headings, lists, tables, formulas, and reading order when returned | Complex geometry may still need review |
| Editable DOCX | Text and recognized structure for editing | May reflow fonts, columns, handwriting, and spacing |
| Original-layout DOCX | Visible source pages with hidden searchable text | The page remains an image rather than rebuilt editable geometry |
| Searchable PDF | Original page appearance plus an invisible text layer | Not a fully tagged accessible PDF |
| JSON and CSV | Engine details, pages, local word positions, and confidence | Local diagnostics may differ from primary structured text |
Task routes add constrained instructions for tables, formulas, bilingual pages, long PDFs, handwriting, invoices, forms, business cards, comparisons, charts, and source-quality checks. They do not validate the truth of extracted values.
The pipeline does not promise perfect language identification, table reconstruction, handwriting, mathematics, semantic field extraction, reading order, or accessibility tagging. Review all consequential output against the source. Remote OCR retention is documented in the privacy policy.
Page reviewed 25 October 2026